How Google Search Works: Crawling, Indexing and Ranking
- Level: Beginner
- #SEO
- #Google Search Console
- #Beginners
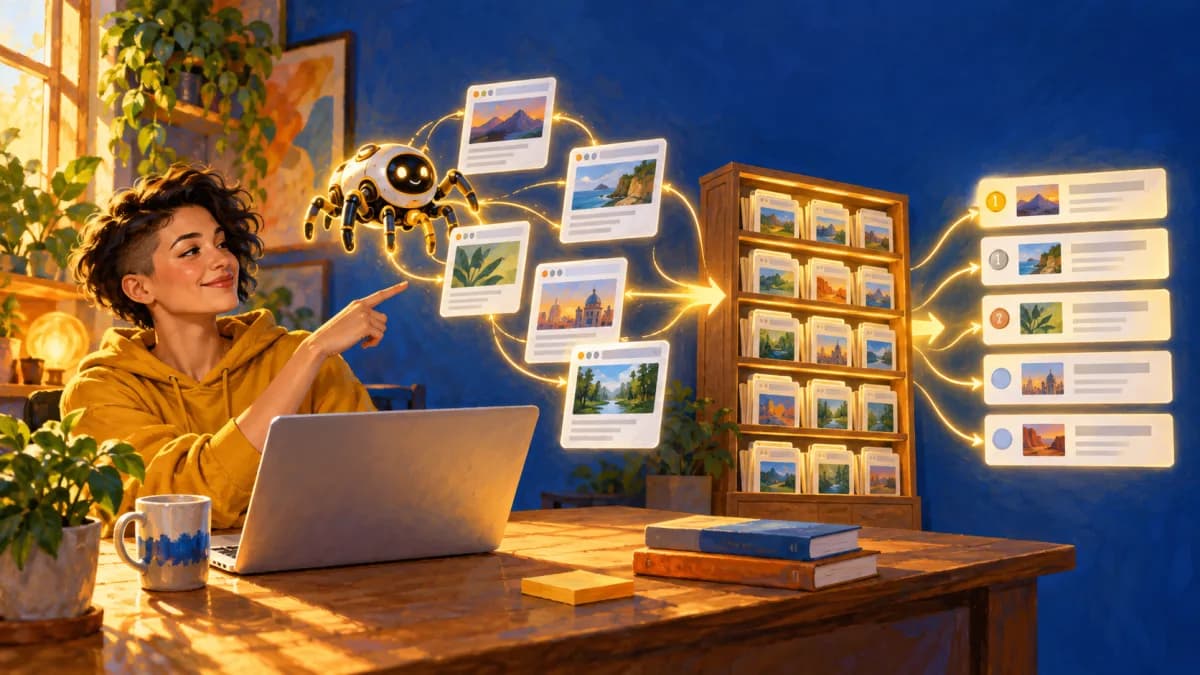
Google works in three stages: it crawls (a program called Googlebot discovers and downloads pages), indexes (analyzes the content and stores it in a database) and serves results (chooses, for each search, what to show and in what order). A page only appears if it gets through all three, and each stage has its own causes of failure.
This guide is part of the complete SEO guide and answers the question that stalls beginners the most: "I published it and it doesn't show up, why?". By the end, you will have a step-by-step process to diagnose it using a free Google tool.
Quick summary
- Crawling is discovering and downloading the page. Google reaches it by following links, revisiting known pages or reading sitemaps.
- Indexing is analyzing and storing. Not every crawled page is indexed, and Google warns that indexing is not guaranteed.
- Ranking (serving results) is choosing, at search time, the most relevant pages from the index. You cannot pay to move up.
- Google renders a page's JavaScript with a recent version of Chrome, but that happens after crawling and can take a while.
- To find out which stage your page stopped at, use URL Inspection and the Page indexing report in Search Console.
How to read this guide: if you are new to SEO, read the first three sections and go straight to the diagnosis steps. If you already work in SEO, focus on the "For SEO professionals" blocks, the status table and the notes on rendering and size limits.
How does Google work, in three stages?
Google works as a chain: it first finds pages, then understands and stores them, and only then decides which ones to show. Anyone who remembers that order can locate a problem quickly, because each stage leaves different clues.
In plain English: imagine a travel guide that maps a city. First, a field team walks the streets and writes down addresses (crawling). Then those notes become a catalog organized by topic (indexing). When a tourist asks "where's a good pizza place around here?", the guide checks the catalog and answers with the most useful options for that person (ranking). If a street is not on the map, none of its pizzerias make it into the catalog.
This structure comes from Google's official documentation on how Google Search works. In practice: before touching a title or a keyword, confirm that the page was crawled and indexed. No content tweak helps a page Google never stored.
What is crawling?
Crawling is Google discovering that a URL exists and downloading its content. It is done by Googlebot, a set of automated programs. It finds pages in three ways: revisiting pages it already knows, following links from one page to another and reading sitemaps submitted by the site owner.
Googlebot has two "modes": Googlebot Smartphone, which simulates a mobile phone, and Googlebot Desktop. According to the Googlebot documentation, both share the same robots.txt token, so you cannot block only one of them using that file.
What gets in the way of crawling:
- No link points to the page. An "orphan" page, which receives a link from no other page, is only found if it is in the sitemap. That is why internal links are part of SEO, and not just navigation.
- robots.txt blocks the URL. The file tells Googlebot where it should not go.
- The server does not respond well. 5xx errors and slowness make Google slow down.
- The link is not a real link. Menus built only with JavaScript, without an
<a href>element, may not be followed.
For SEO professionals: the Googlebot documentation states that it crawls the first 2 MB of a supported file type (64 MB for PDFs) and that, when it reaches the limit, it stops the download and sends only the downloaded portion to indexing. The same limit applies to the CSS and JavaScript resources referenced in the HTML. On pages with bloated HTML (huge embedded JSON, heavy inline CSS), content below the cutoff may never be considered. Check the weight of the raw, uncompressed HTML when long pages lose parts of their indexing. Value checked in the documentation in October 2026.
What is rendering, and why does it matter?
Rendering is Google running the page's code, as a browser would, to see the final content. The documentation explains that, during crawling, Google renders the page and runs the JavaScript it finds using a recent version of Chrome. This matters because many sites only show their text after JavaScript runs.
According to the JavaScript SEO basics guide, pages with a 200 status go into a rendering queue, where they may wait a few seconds, but it can take longer. The same source recommends server-side rendering or pre-rendering, because it makes the site faster for users and bots and because not every bot runs JavaScript. For how AI assistants fetch information, see how LLMs search, RAG and grounding.
In plain English: it is like assembling a piece of furniture. Google receives the box (the HTML) and the instructions (the JavaScript) and only knows what the furniture looks like after putting it together. If the assembly takes a long time or fails, the catalog keeps an incomplete version.
For non-programmers: the main text and the important links should be in the HTML the server delivers.
What is indexing?
Indexing is Google analyzing the page's content (text, images, videos, important tags) and storing it in the index. At this stage it also identifies duplicate pages and chooses a "canonical" version, the one it considers the main one to show in results.
Google's documentation says it plainly: indexing is not guaranteed, and not every processed page will be indexed. Among the reasons cited are low-quality content, robots meta rules that block indexing and a site architecture that is hard to process.
Two distinctions help avoid common confusion:
- Crawled is not the same as indexed. Google can visit the page and decide not to store it.
- Indexed is not the same as well ranked. A page can be in the index and never appear on the first pages of results.
For SEO professionals: choosing the canonical is a Google decision based on signals, not an order. Redirects and
rel="canonical"are strong signals, and presence in the sitemap is a weak signal, according to the documentation on consolidating duplicate URLs. When the report says Google chose a different canonical from the one you declared, it is telling you that your signals contradict each other. The subject continues in technical SEO basics.
How does Google decide the order of results?
When someone searches, Google queries the index and returns the pages it considers most relevant and useful for that person, using hundreds of signals, including location, language and device type. The process is programmatic, and no payment changes the position.
This reinforces two ideas. First, the same search can show different results to different people, so "my position" is always an average. Second, the most relevant page does not have to be the prettiest or the fastest: the page experience documentation says Google always tries to show the most relevant content, even when the experience is poor. But for queries with plenty of useful content, a good experience can make a difference. Speed and stability are measured by the Core Web Vitals.
AI results go through the same front door. Google states that to be shown as a supporting link in AI Overviews and AI Mode, a page must be indexed and eligible for a snippet (see how to optimize for AI Overviews). Without the first two stages, there is no third.
Why doesn't my page show up on Google?
The page does not appear because it stopped at some stage: Google did not discover it, could not access it, discovered it but decided not to index it, or indexed it and it is not relevant enough to appear in visible positions. The Page indexing report in Search Console tells you which stage it stopped at.
The table below gathers the most common statuses, with definitions based on the Page indexing report help. The names may vary slightly depending on the interface.
| Status (as shown in Search Console) | What it means | What to do |
|---|---|---|
| Discovered - currently not indexed | Google found the URL but has not crawled it yet | Wait; strengthen internal links to the page and confirm the server responds well |
| Crawled - currently not indexed | Google crawled it and did not index it, and may index it in the future | Improve the usefulness and uniqueness of the content; avoid near-identical pages |
| Excluded by 'noindex' tag | Google found noindex and therefore did not index it | Remove noindex if the exclusion was not intentional |
| Blocked by robots.txt | robots.txt prevents the URL from being crawled | Adjust the Disallow rule if the page should be crawled |
| Duplicate without user-selected canonical | The page is a duplicate of another and you did not indicate the canonical | Set rel="canonical" to the preferred version |
How do you diagnose it, step by step?
The fastest diagnosis uses Search Console's URL Inspection tool: it shows whether the URL is in the index, when it was last crawled and which canonical Google chose. Follow this order:
- Open Search Console and paste the URL into the inspection bar at the top.
- Read the verdict. "URL is on Google" means indexed. Otherwise, note the reason given.
- Compare with the live test. The indexed page reflects Google's last visit, which can differ from the current version of the site. The live test shows what Googlebot sees now.
- Look for blocks. Check whether there is a
noindexon the page or in the HTTP header and whether robots.txt blocks the URL. - Check the canonical. See whether the "Google-selected canonical" is the URL you want.
- Strengthen discovery. Include the URL in the sitemap and add links from relevant pages that are already indexed.
- Request indexing. Use "Request indexing". According to the tool's documentation, the request does not guarantee that the page enters the index, there is a daily submission limit, and indexing usually takes about a day, but it can take much longer.
For SEO professionals: URL Inspection does not consider every requirement for appearing, such as manual actions, security issues or policy compliance, according to Google's own help. "URL is on Google" is not proof of visibility. Cross-check with the performance report: with no impressions for any query, the page is indexed but is not being shown.
Hypothetical example: the post that disappeared
Hypothetical example: a dental clinic publishes the article "Does at-home teeth whitening work?" on Monday. On Tuesday, the receptionist types the exact title into Google and does not find the page. She concludes that "Google doesn't like the site". That is not quite it.
Before any text adjustment, she opens URL Inspection. The result says "Discovered - currently not indexed". The page is new, and the site has few internal links leading to it. The clinic then takes three simple actions: it adds a link to the article on the whitening services page, confirms the URL is in the sitemap and requests indexing. After a reasonable amount of time, she repeats the inspection.
She did not rewrite the text or buy links: the diagnosis pointed to the right stage (discovery) and the action was proportional. If, weeks later, the status turned into "Crawled - currently not indexed", then it would be worth reviewing the usefulness of the content.
Frequently asked questions
What is the difference between crawling and indexing?
Crawling is Googlebot visiting the URL and downloading the content. Indexing is analyzing that content and storing it in the index so it can appear in searches. A page can be crawled and not indexed, for example because of low quality or a noindex tag.
How long does Google take to index a new page?
There is no fixed deadline. In the URL Inspection help, Google says indexing usually takes about a day, but that it can take much longer in some cases. Factors such as the site's crawl rate and the internal links to the page have an influence.
Does Google rank pages in exchange for payment?
No. The official documentation states that Google does not accept payment to crawl a site more often or to rank it above others, and that ranking is programmatic. Ads exist, but they appear separately and are labeled, with no influence on organic results.
My page is indexed but doesn't show up. Now what?
Indexed only means it is in the catalog. To appear, it needs to be relevant and competitive for the search. Check the performance report for impressions, review the search intent and compare your content with the pages already in the top positions.
Do I need to worry about crawl budget?
Probably not. Google describes crawl budget optimization as relevant for sites with more than 1 million unique pages updated weekly, or more than 10,000 pages with daily changes, or with many URLs in "Discovered - currently not indexed". According to the crawl budget guide, the values are estimates.
Next step
Now that you know at which stage a page can fail, the next guide in the path is technical SEO for non-developers, which explains robots.txt, sitemap, canonical and noindex, plus what to ask the developer for. If you use Contentor, the Results page gathers Search Console data by project, which helps you track impressions and clicks for the pages you just published.
Read also:
Prepare your content for AI answers
Create AEO/GEO briefs, entities, schema, and structured articles for Google AI Overviews, AI Mode, and traditional SEO.
Try Contentor freeStrengthen your authority for AI Search
Combine source-worthy content with contextual backlinks on vetted sites to reinforce trust, discovery, and topical authority.
View contextual backlinks